AI Systems3 min read
Sub-Millisecond Token Scheduling: Inside Disaggregated KV-Cache Paging for Frontier LLMs
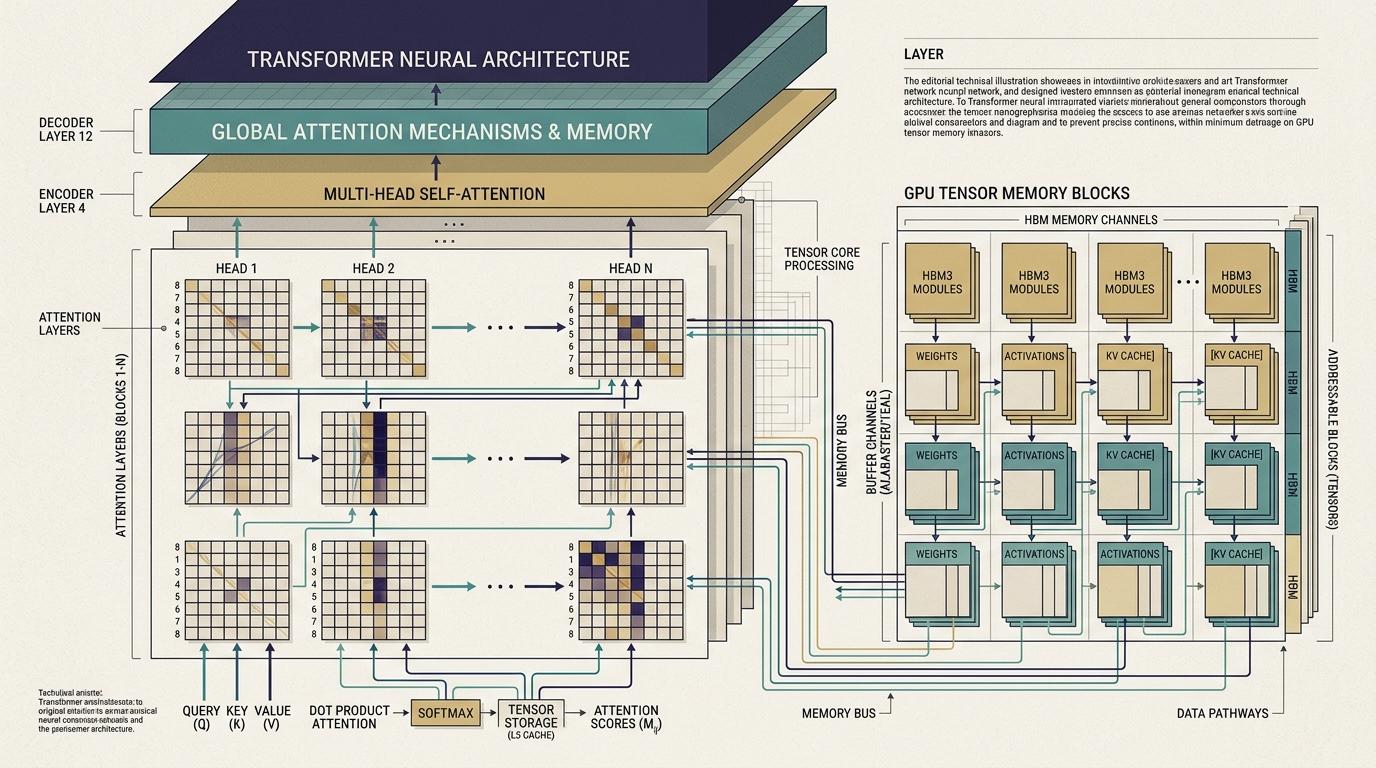
A deep engineering breakdown of virtualized HBM3e memory paging, prefix tree sharing, and decoupled prefill-decode clusters for high-throughput AI inference.
#AI SystemsRead Essay